Ingestion
Log Processor automates the ingestion of your AWS CloudWatch log groups. Logs flow from CloudWatch through Kinesis Firehose to an S3 datalake, where they are indexed into OpenSearch and/or Athena for search and analytics.
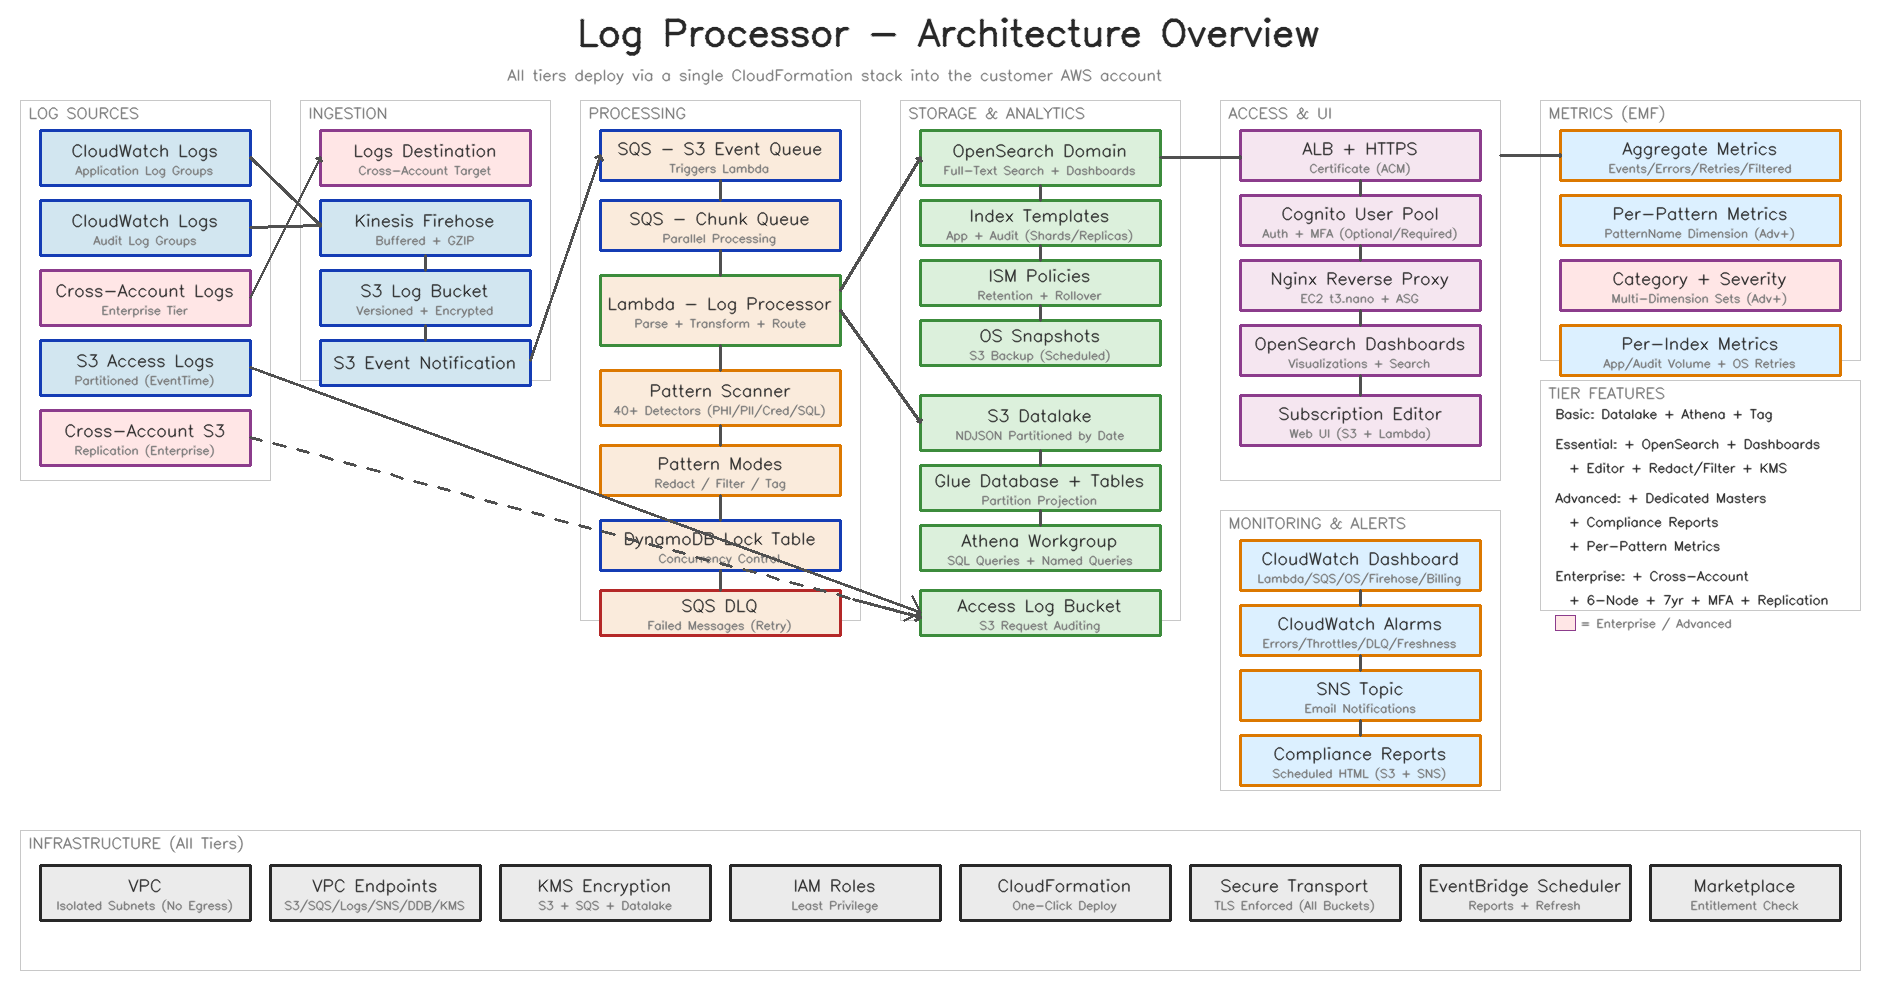
The pipeline
CloudWatch → Firehose → S3 → Lambda → OpenSearch / Athena. Firehose delivery uses configurable buffering and GZIP compression to the S3 datalake. Lambda processes delivered objects in chunks, backed by SQS queues and DynamoDB distributed locking to prevent duplicate processing and ensure reliable delivery.
Automated subscription management
CloudWatch subscription filters are managed automatically using regex-based matching on both log-group names and log-stream names. The pipeline auto-discovers matching log groups so you don't have to wire up each one by hand. Each subscription stream can be routed independently to Athena and/or OpenSearch, so you can send verbose or high-volume logs to the datalake only while sending critical application and audit logs to both.
Cross-account capable
Ingestion is cross-account capable. On the Enterprise tier you can centralize logs from multiple AWS accounts into a single pipeline using a CloudWatch Logs destination, with per-account tagging. See Cross-Account Ingestion for details.
Reliability
- Chunked processing via Lambda and SQS for reliable delivery.
- Distributed locking via DynamoDB to prevent duplicate processing.
- Dead letter queues and CloudWatch alarms for Lambda errors, DLQ depth, and Firehose freshness. See Monitoring Dashboard.
Configurable sizing and retention
Firehose buffering, computational resources, disk space, and retention policies are all configurable through your deployment tier. See Retention.